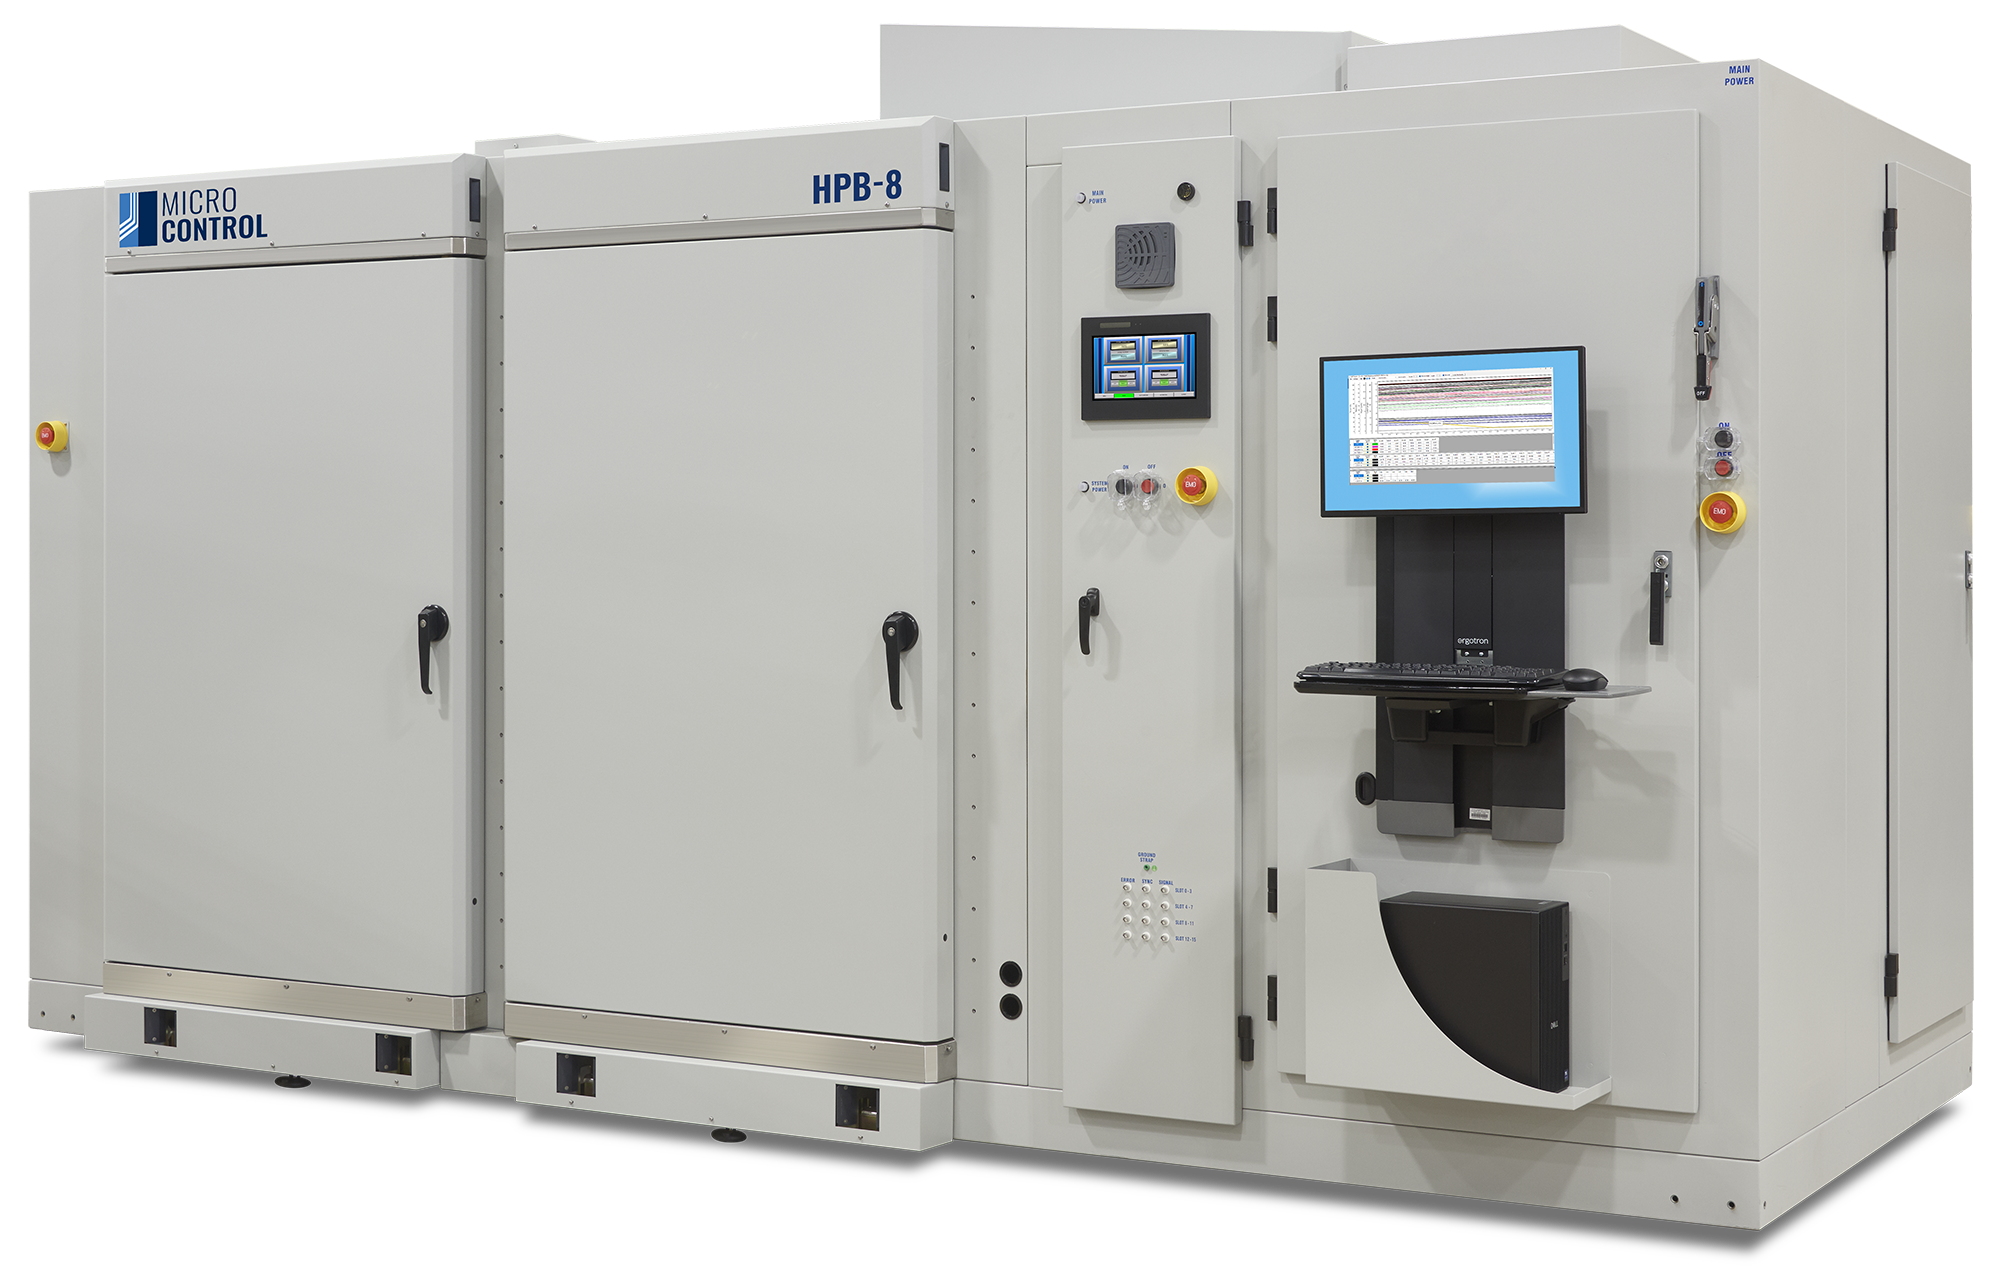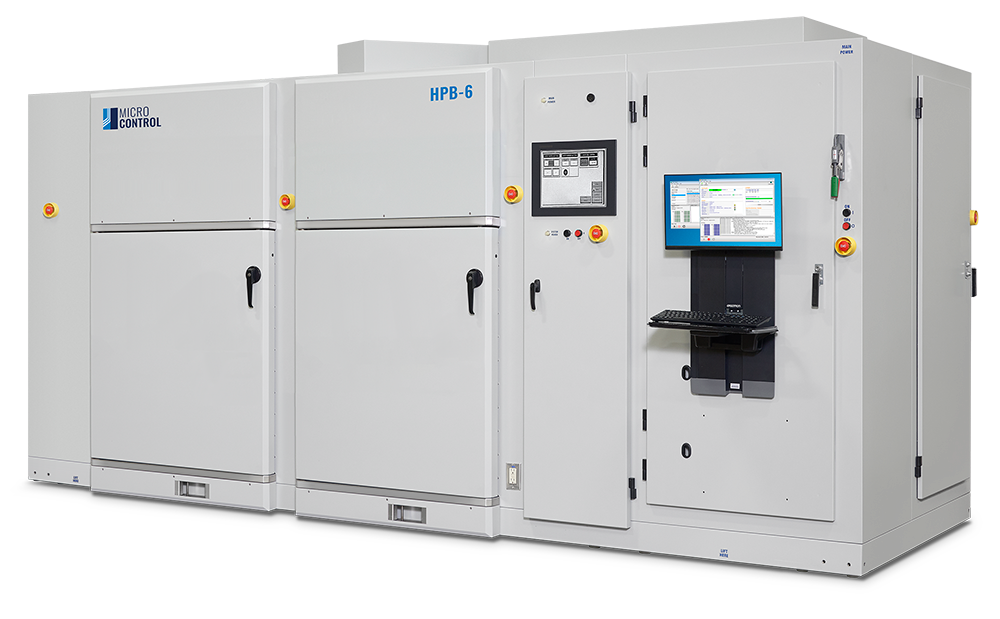
The semiconductor devices at the heart of AI and high-performance computing, accelerators, processors, memory, and interconnects are designed to operate near their performance limits for extended periods of time. In data center and cloud environments, that means sustained electrical and thermal stress, high utilization rates, and limited tolerance for early-life failures that can disrupt workloads and increase operational cost. Burn-in with test supports AI and HPC devices by helping identify latent defects and validate device robustness before deployment, where the cost of a failure is far higher than the cost of screening.
Key Specifications
- Supports engineering qualification and production screening for high-power compute devices
- Applicable to AI accelerators, GPUs, CPUs, high-bandwidth memory, and interconnects
- Addresses early-life failure risks associated with sustained high-load operation